Automated BI Pipeline with AI Enrichment
Orchestrated ETL data warehouse with pandas transformations, AI enrichment, and Streamlit analytics.
THE STORY
Disparate data sources across e-commerce, CRM, and support tickets lead to broken metrics. This pipeline extracts raw data across 5 channels, cleanses it with pandas, enriches reviews and tickets via LLM classification, and populates a PostgreSQL data mart powering a Streamlit BI dashboard.
MY CONTRIBUTIONS
- Engineered multi-stage ETL DAG in Apache Airflow with retries and task dependencies.
- Built PostgreSQL data mart with raw landing schema and enriched mart analytical views.
- Developed bilingual English/French Streamlit BI dashboard displaying revenue analytics and support sentiment.
- Integrated WeasyPrint automated PDF summary report generation distributed to stakeholders.
- Implemented cost-controlled mock enrichment layer allowing $0.00 offline execution testing.
Solution highlights
Consolidates 5 raw data channels into an enriched PostgreSQL data warehouse powering real-time Streamlit dashboards and automated PDF reports.
The problem
E-commerce teams spend hours manually matching CSV exports from Shopify, Zendesk, and Salesforce, leading to delayed reporting.
The insight
Combining deterministic SQL transformations with targeted LLM sentiment enrichment produces insights that raw spreadsheets cannot capture.
Explorations & iterations
Designed DAG DAG dependency trees to ensure raw landing tables finish loading before enrichment tasks execute.
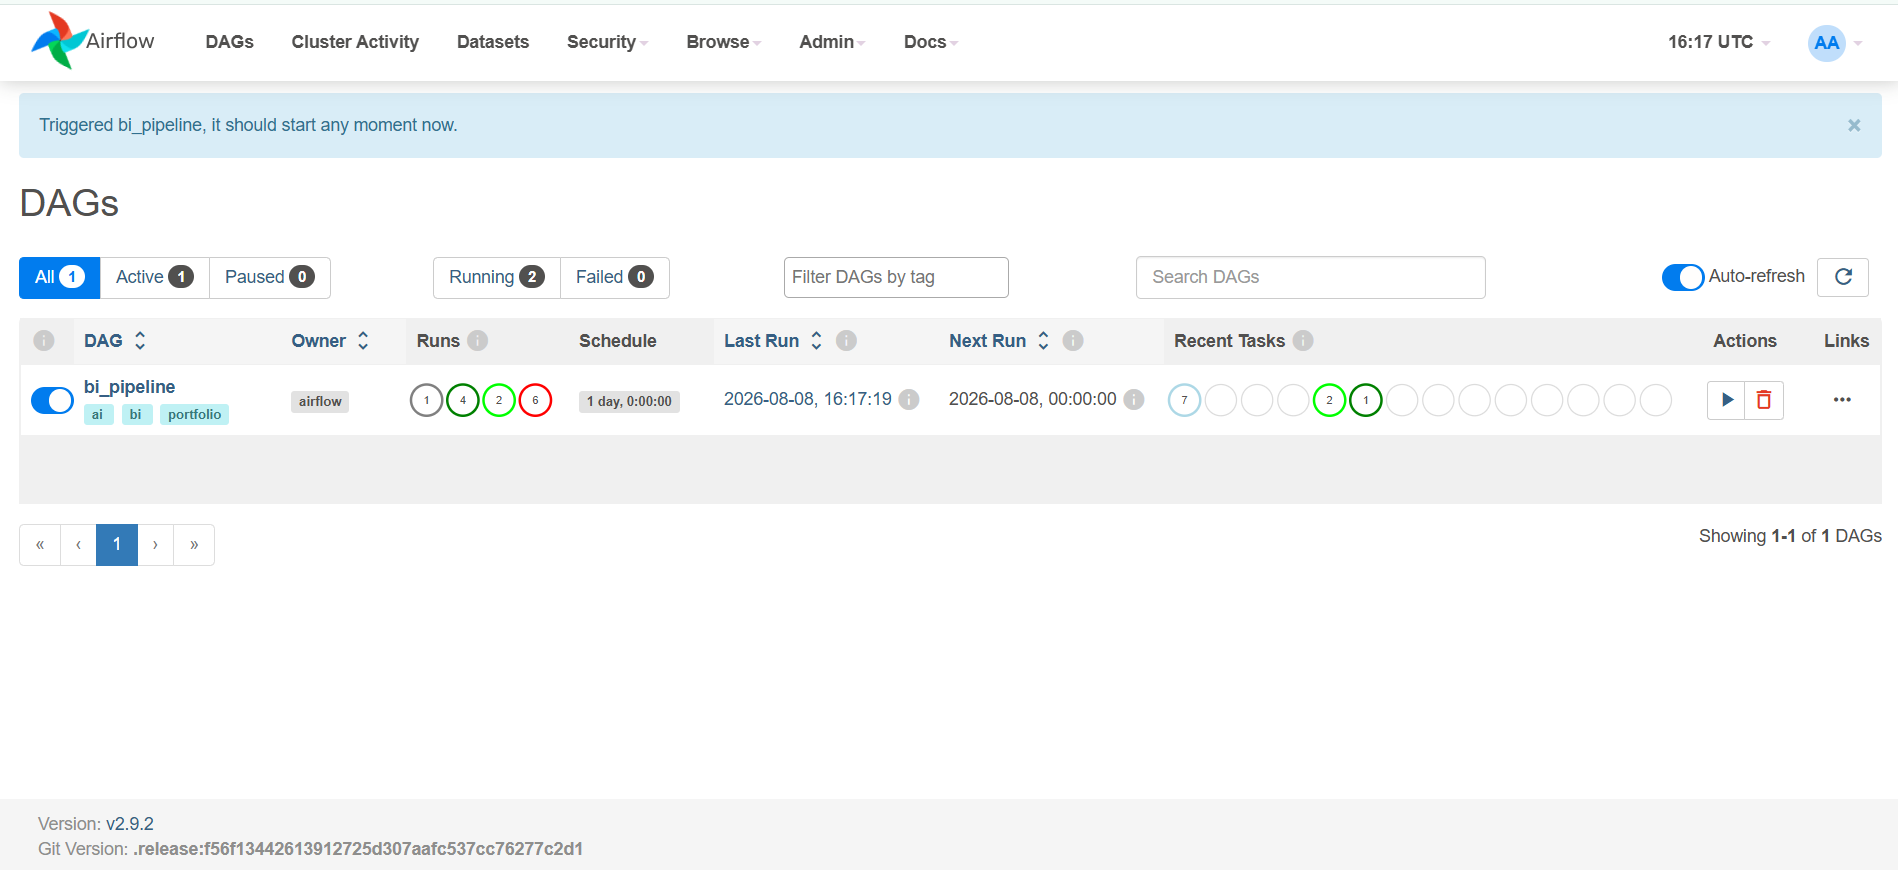
Artifact 01: Airflow Orchestrator
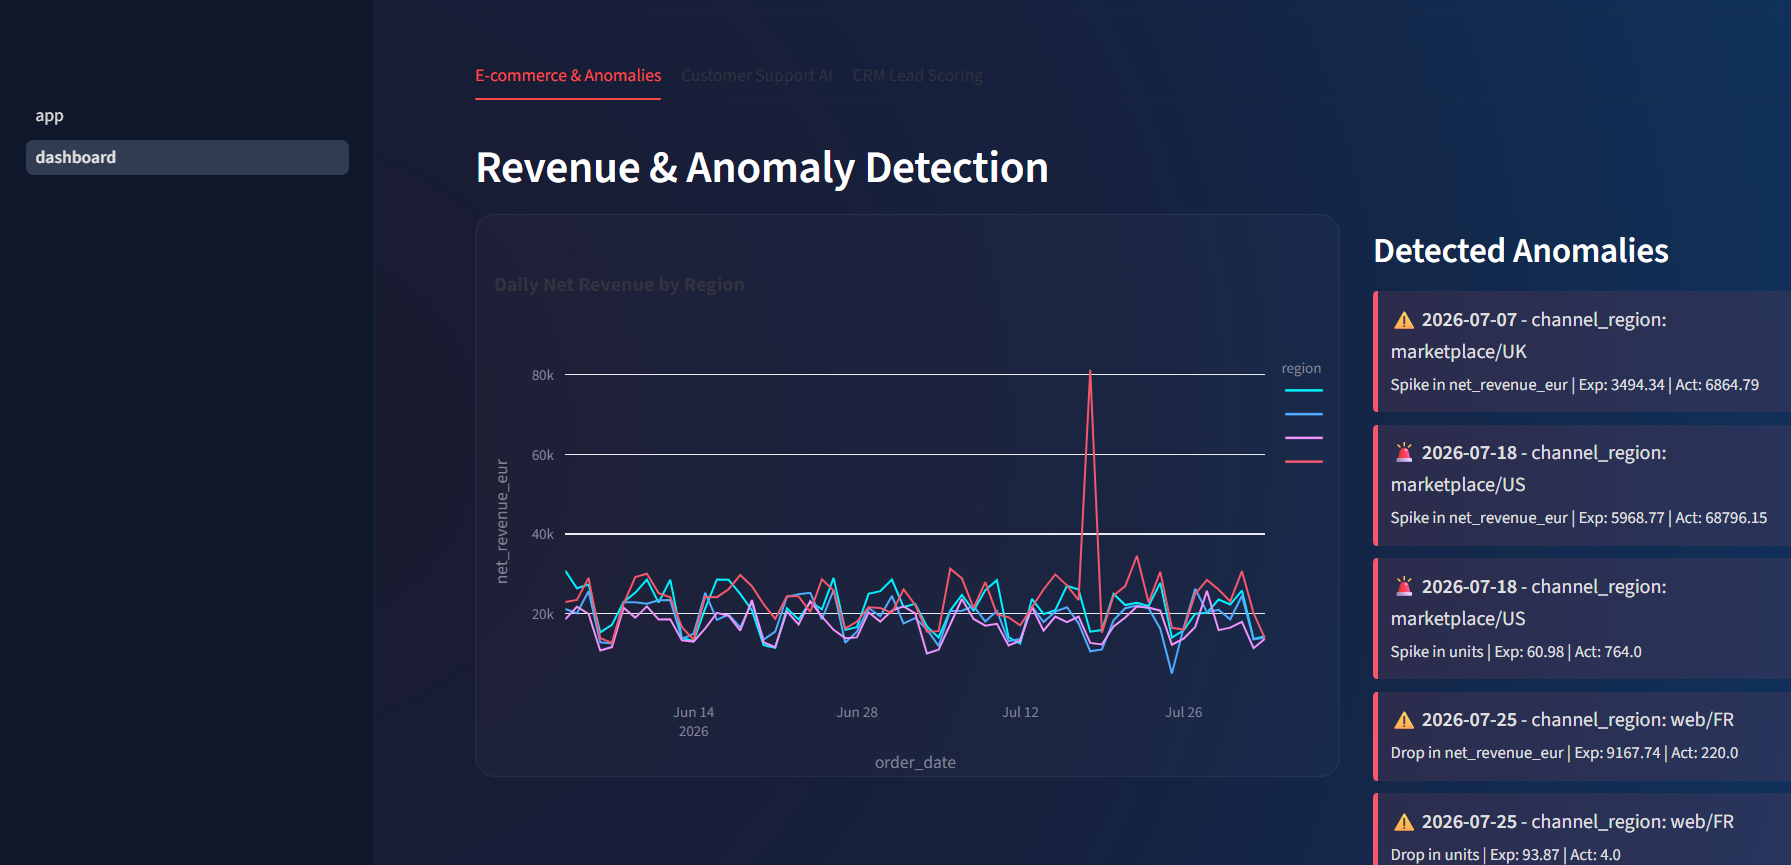
Artifact 02: Streamlit Analytics
Up close: Data architecture
CSV Seed Data → Airflow Extractor → Pandas Transformer → Postgres Raw → LLM Enricher → Postgres Mart → Streamlit & WeasyPrint PDF.
Under the hood
Airflow DAG definition enforces strict task order and dependency checks.
with DAG("bi_ai_pipeline", schedule_interval="@daily") as dag:
    extract_task = PythonOperator(task_id="extract_raw_data", python_callable=extract_all)
    transform_task = PythonOperator(task_id="transform_and_enrich", python_callable=enrich_mart)
extract_task >> transform_taskFailure modes & guardrails
If LLM endpoints experience timeouts, the enricher gracefully falls back to rule-based keyword classification without halting the ETL pipeline.
Measurable impact
Eliminated manual spreadsheet aggregation and enabled instant bilingual reporting for business stakeholders.
Reflection / what I learned
Designing pluggable mock providers for LLM steps allows full CI/CD test automation without incurring API token costs.